Most of what you spend on AI agents buys sentences your own code reads once, parses into a yes or a no, and throws away. That waste belongs in any AI cost management review, and most of it can go without signing a new contract.
TypeSafe released Jev AI on 15 September to headlines about how much faster and cheaper than an LLM it is. For a Microsoft estate the useful comparison is with the Model Router in Microsoft Foundry (formerly Azure AI Foundry), and the two do different jobs. Model Router picks which LLM answers each call your agents make.
Jev AI replaces the LLM on the calls whose answer is a label, such as a department, a yes or a no. Since 25 September TypeSafe also offers Jev Router on OpenRouter, which picks the model for each request the way Model Router does, but it runs outside your Azure tenant.
So the real question for IT is how many of your agents’ calls are labels.
- Jev AI and Model Router fix different calls. Understand which calls each one can touch.
- Most of your model calls return text nobody reads. Learn to count them in your Foundry logs.
- Those calls cost you three ways. Only one shows up on a bill.
- Foundry Model Router charges for control. Learn what the routing fee and data residency cost you.
Jev AI Exists Because Language Models Are Doing Work They Were Not Built For
David Linthicum, an independent technology consultant, summed up its appeal in InfoWorld: using a general-purpose LLM when the application only needs a bounded decision is "like using a full enterprise service bus to answer a yes/no routing question." Nearly 13% of the paid teams on Vercel's AI Gateway tried it within 24 hours, which reads as recognition more than adoption.
What the launch could not tell anyone is how much of that work sits in their own systems, or whether Microsoft already sells a fix.
Jev AI and Model Router Cut the Same Bill in Different Places
The two are easy to confuse: both are small models sitting between your code and a language model, making one fast decision per request. What they decide differs.
Model Router decides which LLM answers. Every prompt still reaches a generative model and you still get text back. It saves money by sending easy prompts to cheaper models.
Jev decides the answer itself, when the answer is one of a fixed list. You pass the question and the permitted options, you get one option and a probability back, and no LLM runs at all.
Neither is aimed at the questions your users type. The calls in question are the ones your agents fire on their own, between request and reply. One customer email to a support agent can trigger five:
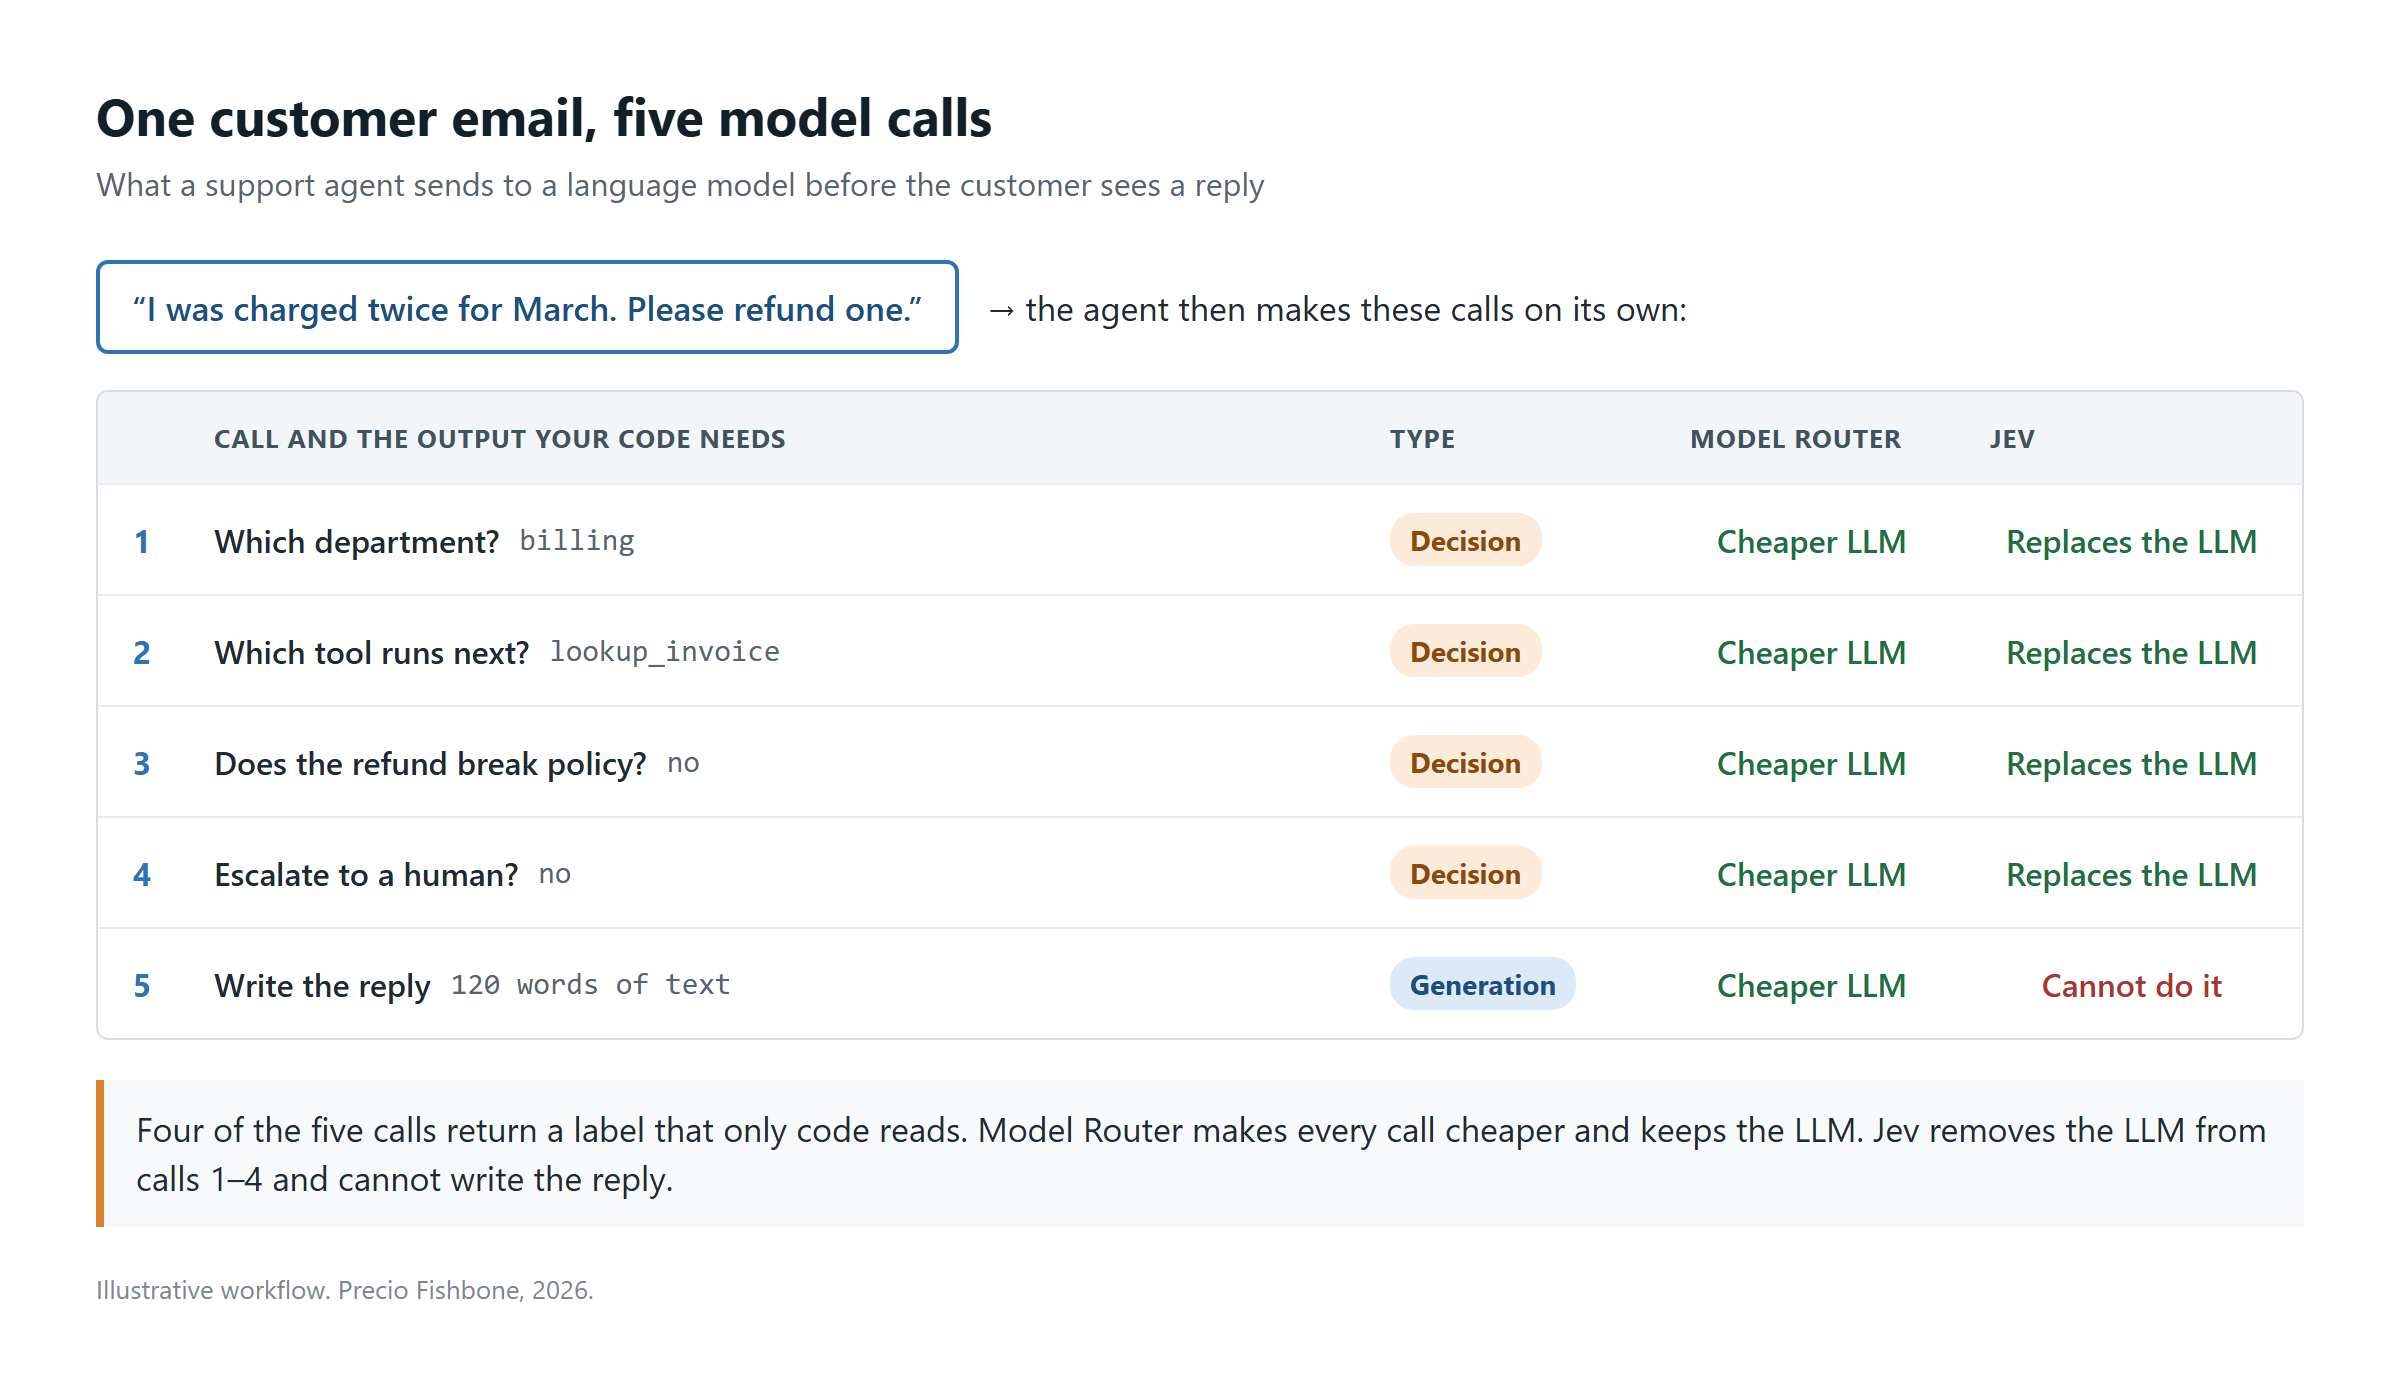
Figure 1. One customer email, five model calls. Four return a label only code reads. View full-size image
Model Router can make all five calls cheaper. Jev can replace the first four but cannot write the reply, the honest limit of any Jev AI agent design. So the comparison becomes a count: what share of your calls look like the first four?
Most of Your Model Calls Return Text Nobody Reads
A call is a decision call if its output is read only by code, parsed into a branch or a score, and never shown to a person. Picking an agent’s next tool counts; summarizing a document does not. The plumbing between agent steps is where the volume sits.
You can count these without buying anything. Every Chat Completions response carries a model field naming the model that served it, and Microsoft's guidance is blunt: log it and build dashboards on it. Monitoring > Metrics split by underlying model shows where the tokens go; Cost analysis filtered by deployment tag puts a number on it. The same exercise works on GitHub Copilot, which has its own token waste playbook.
Expect the answer to be unflattering. In Microsoft's own sample response, 128 of the 163 output tokens are reasoning the caller never sees. Put that deliberation behind a question with three possible answers and you are paying for thinking in service of prose your parser discards on arrival.
A count is not yet a cost, so price what a wasted decision call charges you.
Decision Calls Cost You Three Ways
Unit price is the visible part. Jev AI charges $0.042 per million input tokens with free output, against about $0.20 to $5 for the generative models in the Foundry pool. That gap is real, and it is the smallest of the three problems.
Latency is the second, and it compounds. TypeSafe advertises a tenth of a second; a generative model takes seconds. In an agentic AI workflow you pay that on every turn, so twelve decision points cost twelve delays before any useful work happens.
The third charge appears in no budget line: retries when the model returns text that breaks your schema. Every team I talk to has that retry branch, usually written by whoever was on call that week, and none can say how often it fires.
Add those up and the case for a specialist decision model looks strong, but it rests on the vendor's own figures. Has anybody checked them?
Independent Tests Found the Same Capability for Far Less
TypeSafe's headline figures are 193.6x faster and 444.6x cheaper, from internal evaluations with no public benchmark. Independent testers answered within a week, starting with Laya, an Apache 2.0 reproduction of Jev AI that appeared three days after launch.
On the held-out split of the LocalLLaMA/typed-decisions set, 2,000 decisions from financial, security, support and agent-trace workflows:
| Model | Size | Accuracy | Brier score |
Jev 1.13.0 |
~150M | 72.70% | 0.1480 |
| Laya (open) | 421.3M | 76.60% | 0.0660 |
openJev-verdict-2.0 |
149.6M | 77.10% | 0.0636 |
Read the Brier column first. It measures whether stated probabilities match reality, which is TypeSafe's central claim, and both open models beat Jev on it.
On a phishing set neither model was trained on, Jev scored 0.626 against 0.813 for Claude Haiku 4.5, a small generative model.
Hold this loosely: these are one-person benchmarks, and one author writes that his suite "is not a Benchmark." The direction is still clear. A nine-hour fine-tune on a six-year-old consumer GPU matched a funded vendor's model under Apache 2.0, and nobody rebuilds a vendor stack around a capability that cheap to copy.
So the vendor's edge is thinner than advertised. What do you actually change?
Three Routes Cut LLM Decision Cost, in Rising Order of Effort
The first changes the price and nothing else. Model Router picks a cheaper model per request within a quality band you set: Balanced holds within roughly 1–2% of the best model's quality, Cost widens that to about 5–6%.
The second is your own small model, such as Phi. Microsoft's small models sit outside the router's pool, so you deploy and operate that one yourself.
The third removes the language step, through Jev or a classifier you train yourself. Only this one changes the architecture: one layer reasons, another judges.
| Route | What changes | What it costs you |
| Model Router | Cheaper model per request | A routing fee on every input token; savings capped by the quality band |
| Your own small model | You own the decision model | Engineering time, evaluation, lifecycle |
| Non-generative decision layer | The language step disappears | A second vendor, a second DPA, a new audit problem |
The table shows what each route costs; the figure below shows which steps survive. Model Router keeps the text, the parser and the retry branch. A small model you host still returns text. Only a decision model hands back the label itself, with a probability your code can act on.
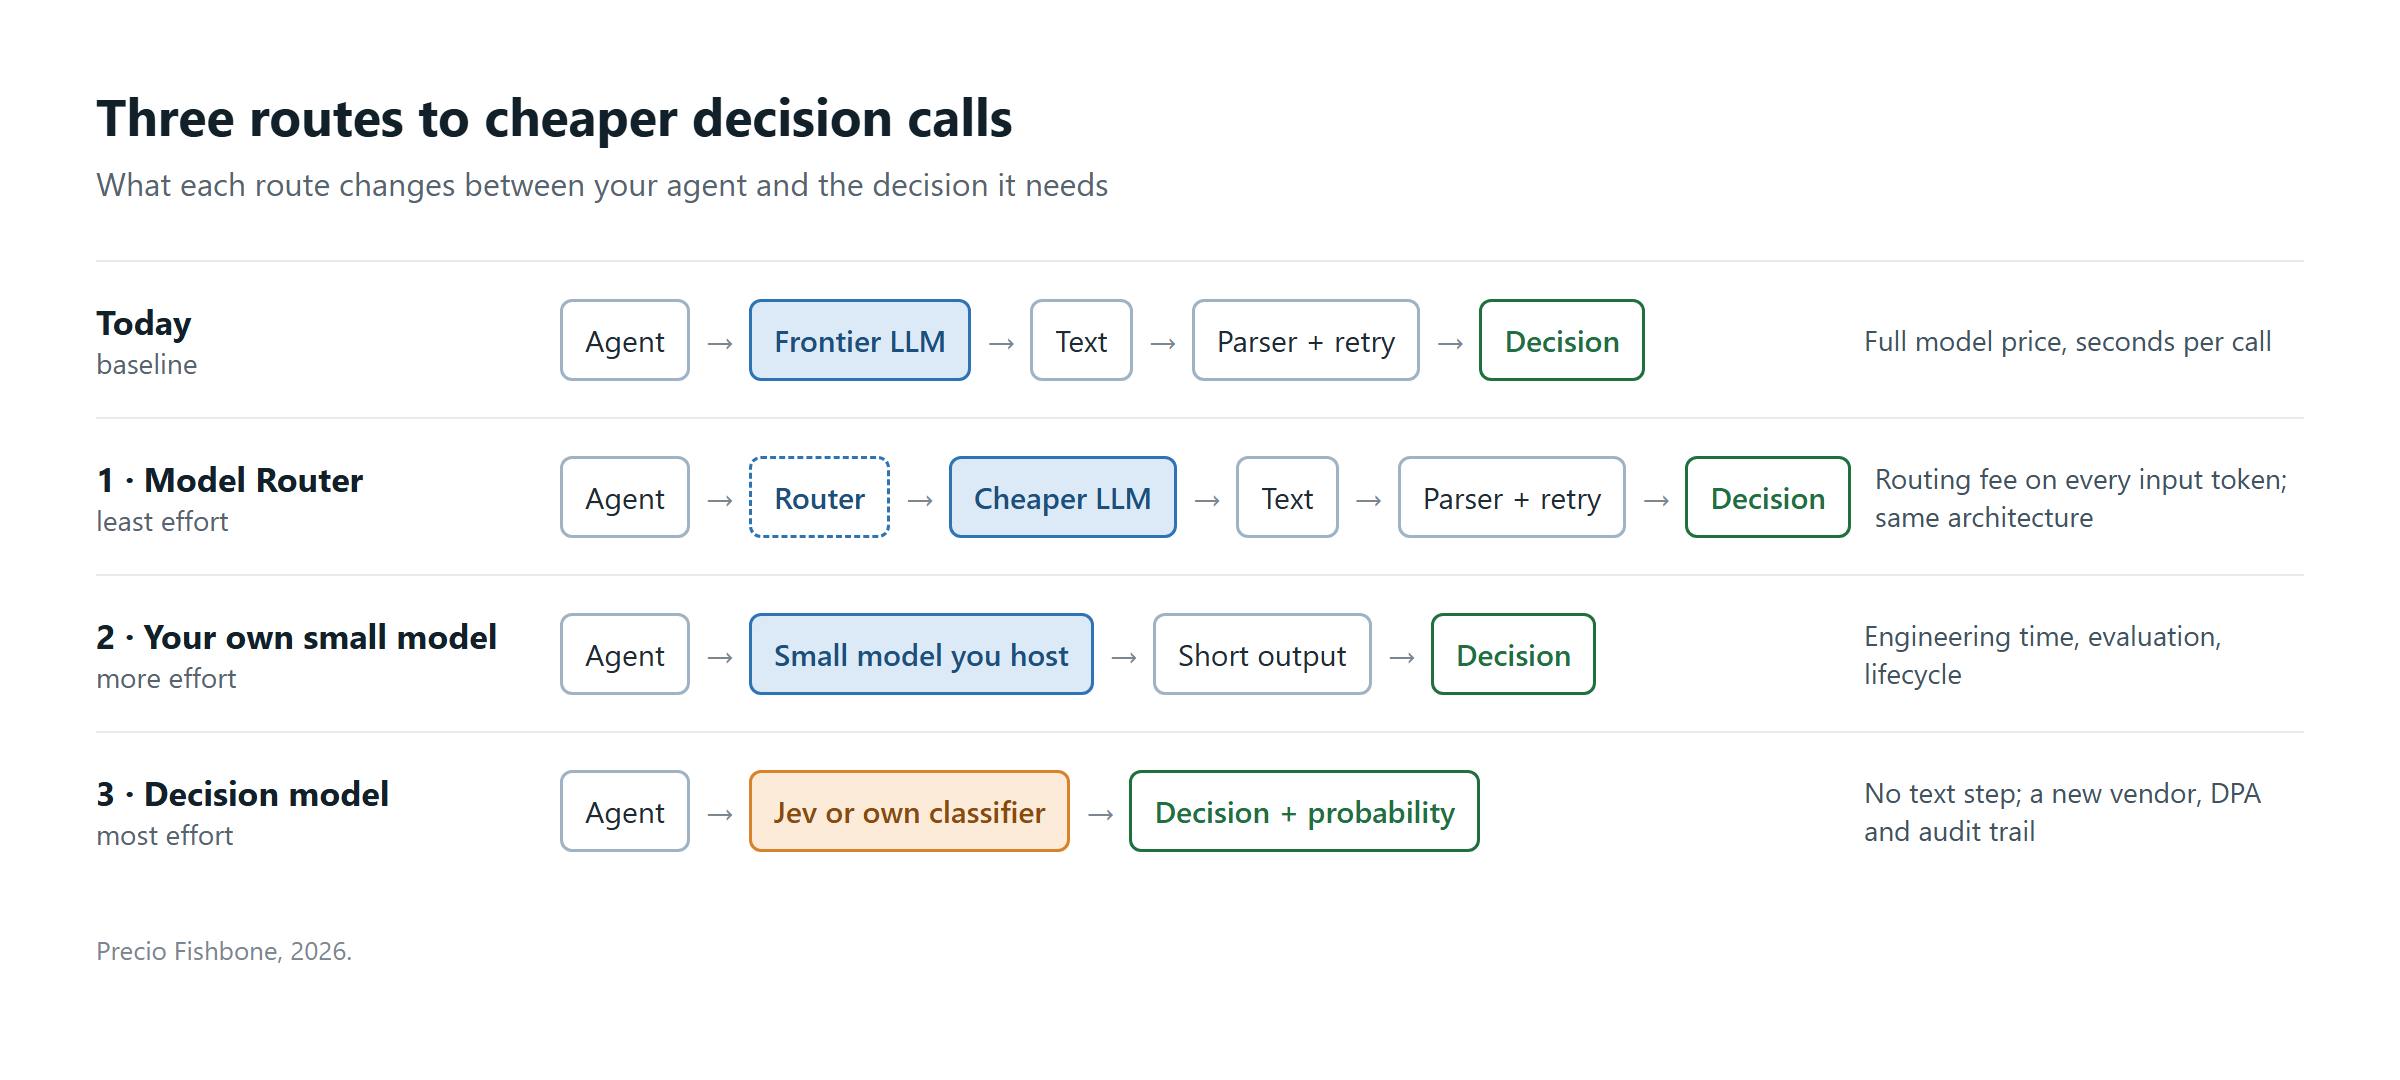
Figure 2. What each route removes between your agent and the decision. View full-size image
For most Microsoft estates the first route is where to begin, and the reason has little to do with price.
Microsoft Foundry Model Router Trades Unit Price for Control
On unit price, Microsoft loses this argument. Model Router bills a routing fee on input tokens, listed at $0.14 per million on Global Standard and $0.154 on Data Zone Standard, on top of the model that serves the request. It also leaves the other two charges untouched: you still parse text and you still keep the retry branch.
There is a case that settles the other way. One high-volume classifier, millions of decisions a day, no residency requirement and no regulator asking how it decided. There the specialist model wins on arithmetic, and I would say so in the meeting.
Residency and governance are what you actually buy
You give up unit price and get jurisdiction back. Sweden Central and Norway East support Data Zone Standard, the router honors data zone boundaries and stores no prompts, model subset and Azure Policy fix which models may serve traffic, and agent identities stay in Entra Agent ID.
That control has a price no invoice shows. At Tier 1, Microsoft's quota table gives Data Zone Standard 300 requests per minute against 1,000 on Global Standard. Residency costs roughly 70% of your throughput headroom at every tier, so price it in before it becomes a capacity incident.
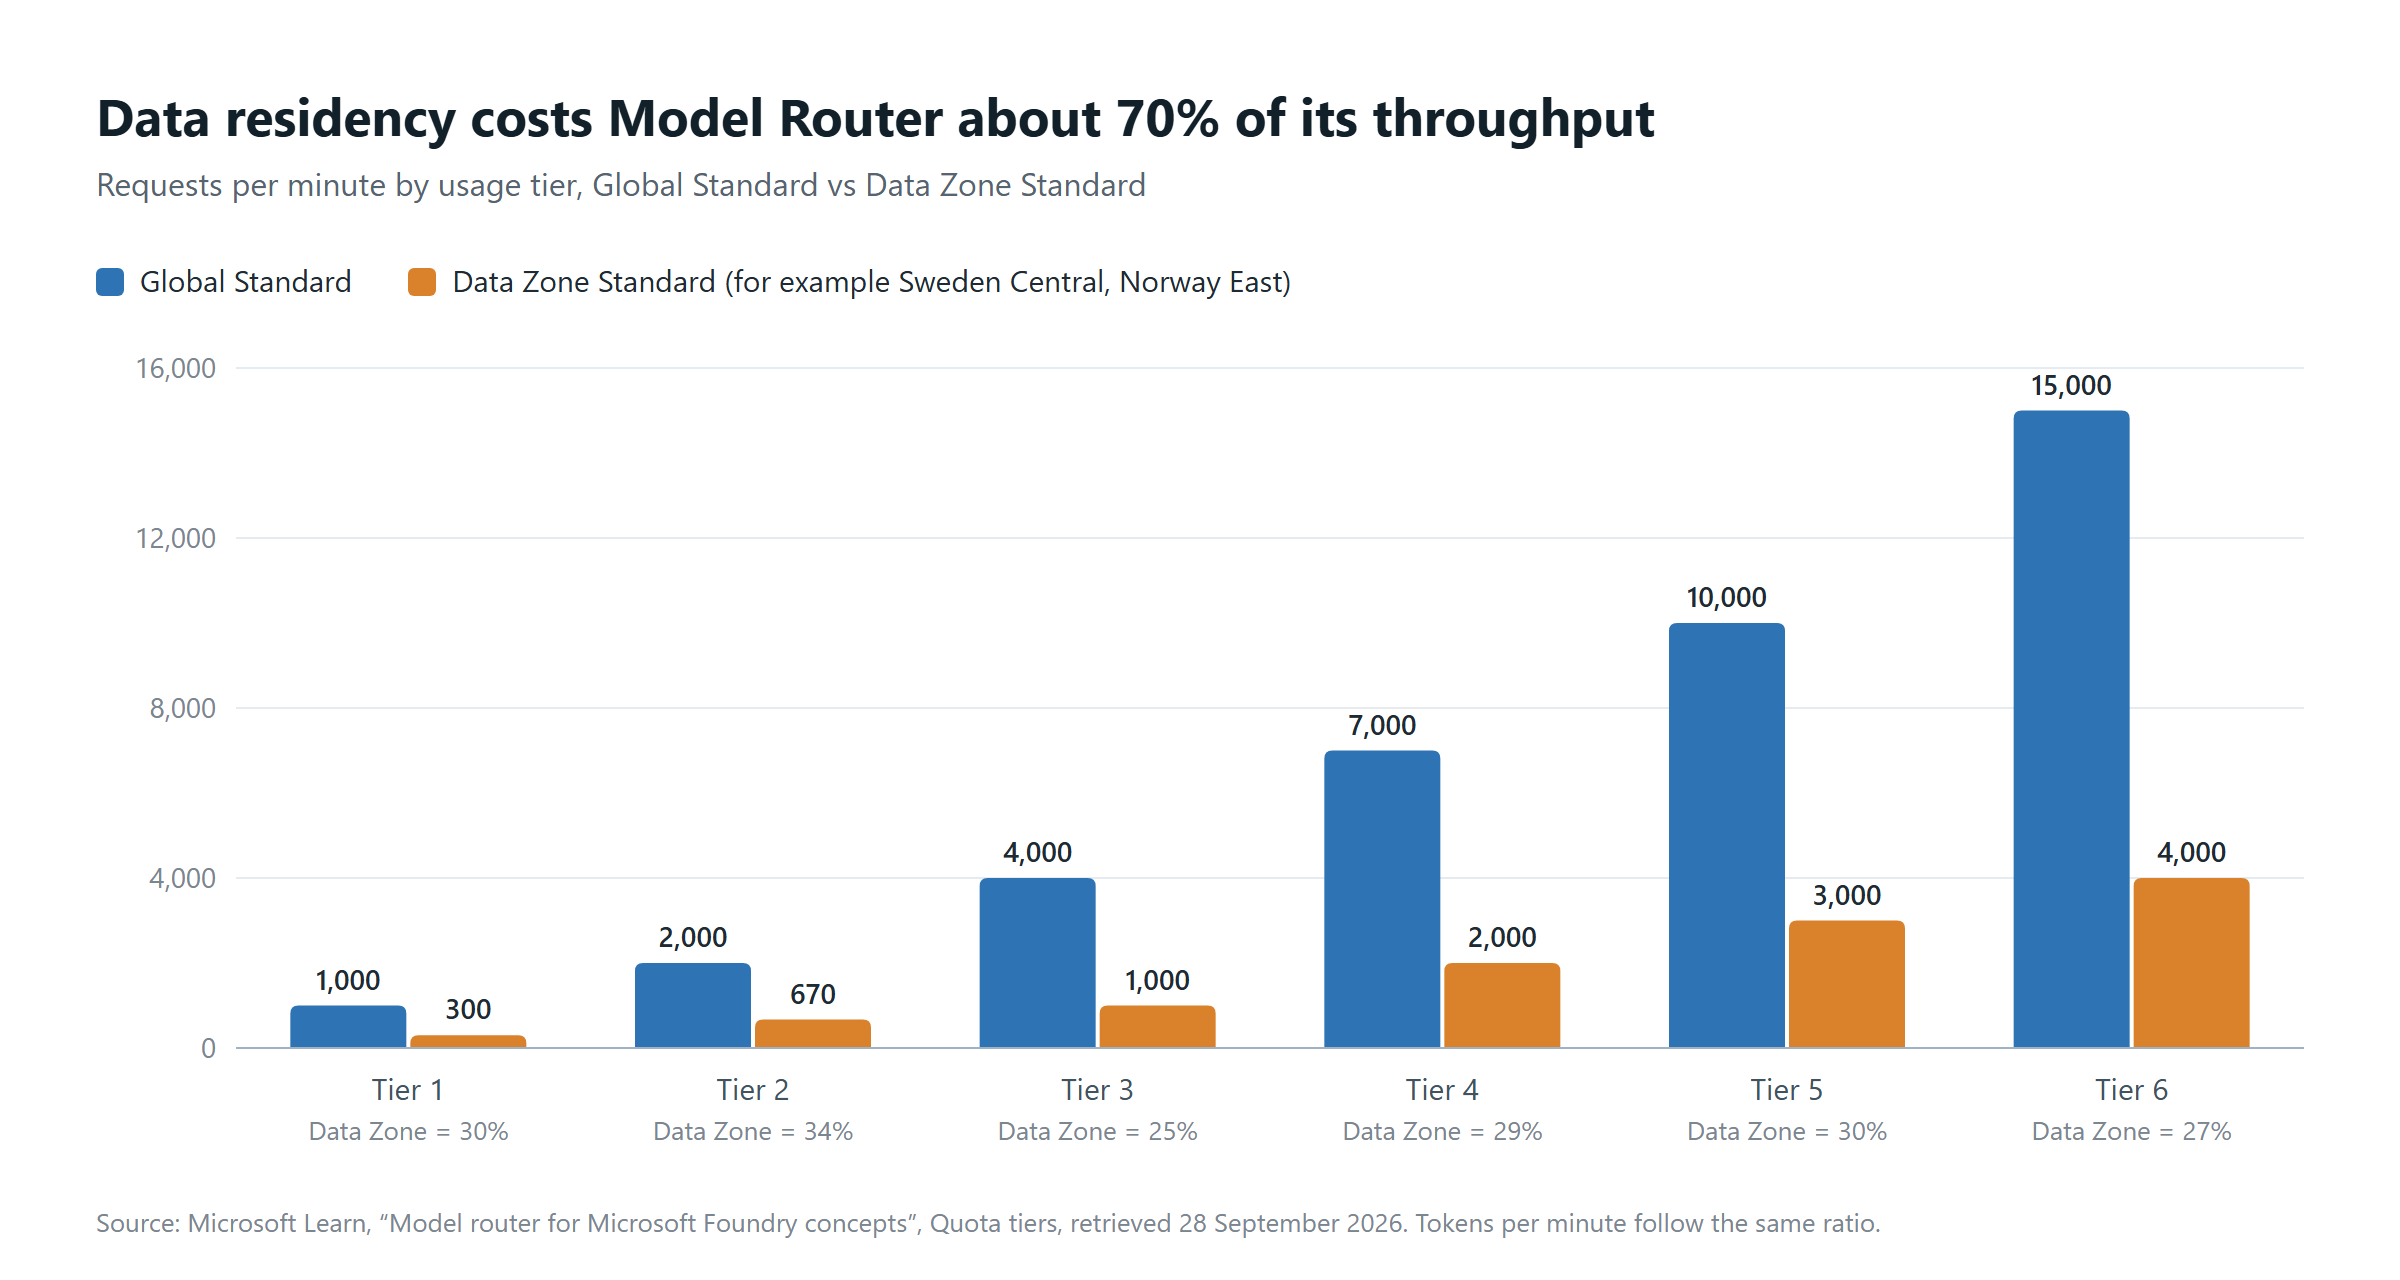
Figure 3. Model Router quota by tier. Source: Microsoft Learn, Quota tiers. View full-size image
A new vendor brings its own bill. A VentureBeat security review found injected text moving Jev's verdicts, and a decision leaves no prose behind, so a regulator will not take 0.83 as an explanation.
Microsoft already runs a decision model of its own
Model Router is not an LLM. It is a lightweight, purpose-built model that reads a prompt and returns one decision, which model should serve it, in a sample trace documented at 19 milliseconds.
Microsoft charges $0.14 per million input tokens for that routing decision alone, more than three times what TypeSafe asks for a decision of your choosing. You just cannot ask Microsoft's model your own questions. The gap is commercial, not technical.
Counting Comes Before Buying
None of this needs a purchase order, just about a week of somebody's attention, mostly spent reading logs.
- Count first. Log the model field and work out what share of calls in your busiest workflow return text nobody reads.
- Replay before you change anything. Microsoft's docs link a community distribution tool that runs your own prompt corpus across routing modes.
- Start in Balanced, then tune. Move batch work to Cost mode after a few weeks, and keep at least two approved models in the subset so failover survives.
- Only then price the vendor question. Route three earns a business case if decision calls run beyond roughly a tenth of your model spend, or if one user action fires more than ten of them.
In most estates I have looked at, the answer is a routing change and a smaller model rather than a Jev AI contract. The advantage is in the harness around the model, and it will still be there next quarter when everyone is quoting a different model.
Work with Precio Fishbone
Not sure which of your AI workloads actually need a frontier model? Book a free consultation with our AI team, or email me directly at par.johansson@preciofishbone.se.
Book a free consultationFrequently Asked Questions
How much does Jev AI cost compared with an LLM?
$0.042 per million input tokens with free output, against roughly $0.20 to $5 for the generative models in Foundry. The saving on your bill depends on how much of your spend is decision calls.
How much does Microsoft Foundry Model Router cost?
A routing fee on input tokens, listed at $0.14 per million on Global Standard and $0.154 on Data Zone Standard, plus the token price of whichever model it picks. Microsoft Learn confirms the router fee, though one how-to page still omits it, so check the pricing page for your region before you build a business case.
Is Jev AI open source?
No. TypeSafe has released neither weights nor training details. Open reproductions such as Laya and openJev-verdict match or beat Jev on typed-decision accuracy; check their licenses before commercial use.
Should we replace our LLM with Jev AI?
No. Generation and dialogue still need a language model. Run both, with the cheap layer deciding where the expensive one gets used.
Is Jev AI available on Azure or in Microsoft Foundry?
Not as of 28 September 2026. Jev is not in the Microsoft Foundry model catalog. You reach it through TypeSafe's own API, Vercel AI Gateway, OpenRouter or Cloudflare Workers AI, so every call leaves your Azure tenant. A request to support Jev in Microsoft Agent Framework (issue #8556) is open and assigned to maintainers, but nothing has shipped. If data has to stay in an EU data zone, your options today are Foundry Model Router or an open-weight decision model you host yourself.
Share this on
Pär Johansson
Pär works with international business at Precio Fishbone, project delivery & digital services, helping turn complexity into progress and strategy into long-term value. With many years of experience in international business, He is known for building strong relationships and turning plans into meaningful progress. Driven by people, trust and sustainable growth.