On 15 September 2026, a San Francisco company called TypeSafe released a model named Jev. Three days later Vercel published its adoption numbers: almost 13% of the paid teams on its AI Gateway inside 24 hours, more than twice any previous model launch.
That level of adoption raises a question: what is Jev actually doing differently? It does not generate text, and that changes how you judge its capabilities, limits, speed and cost.
- What does Jev actually do? The shape of a Jev call, before the marketing numbers.
- Where does a decision model fit? Next to the rules, classifiers and LLMs you already run, each with its own job.
- What is Jev good at, and what breaks it? TypeSafe publishes its own failure list.
- What does it cost and how fast is it? And how much weight the headline multiples carry.
What Jev Is
Take a support ticket: “I was charged twice for the same order. Can someone look into this?” Today you would send it to an LLM with a prompt asking for JSON, get back a sentence wrapped around it, parse that, and add a retry for when the shape comes back wrong.
With Jev you send the ticket text as state and a typed question beside it: which department handles this, with billing, technical and account as the options. Back comes choice: “billing”, a probability for each option, and a confidence value. Nothing to parse, and no branch for malformed output, because the answer can only be an option you supplied.
Jev is TypeSafe’s flagship model and the first of what the company calls System One models; outside TypeSafe the category is usually called decision models. It reads natural language like an LLM, accepts text only, and never produces prose or code. LLMs produce words for people; Jev produces typed decisions for software.
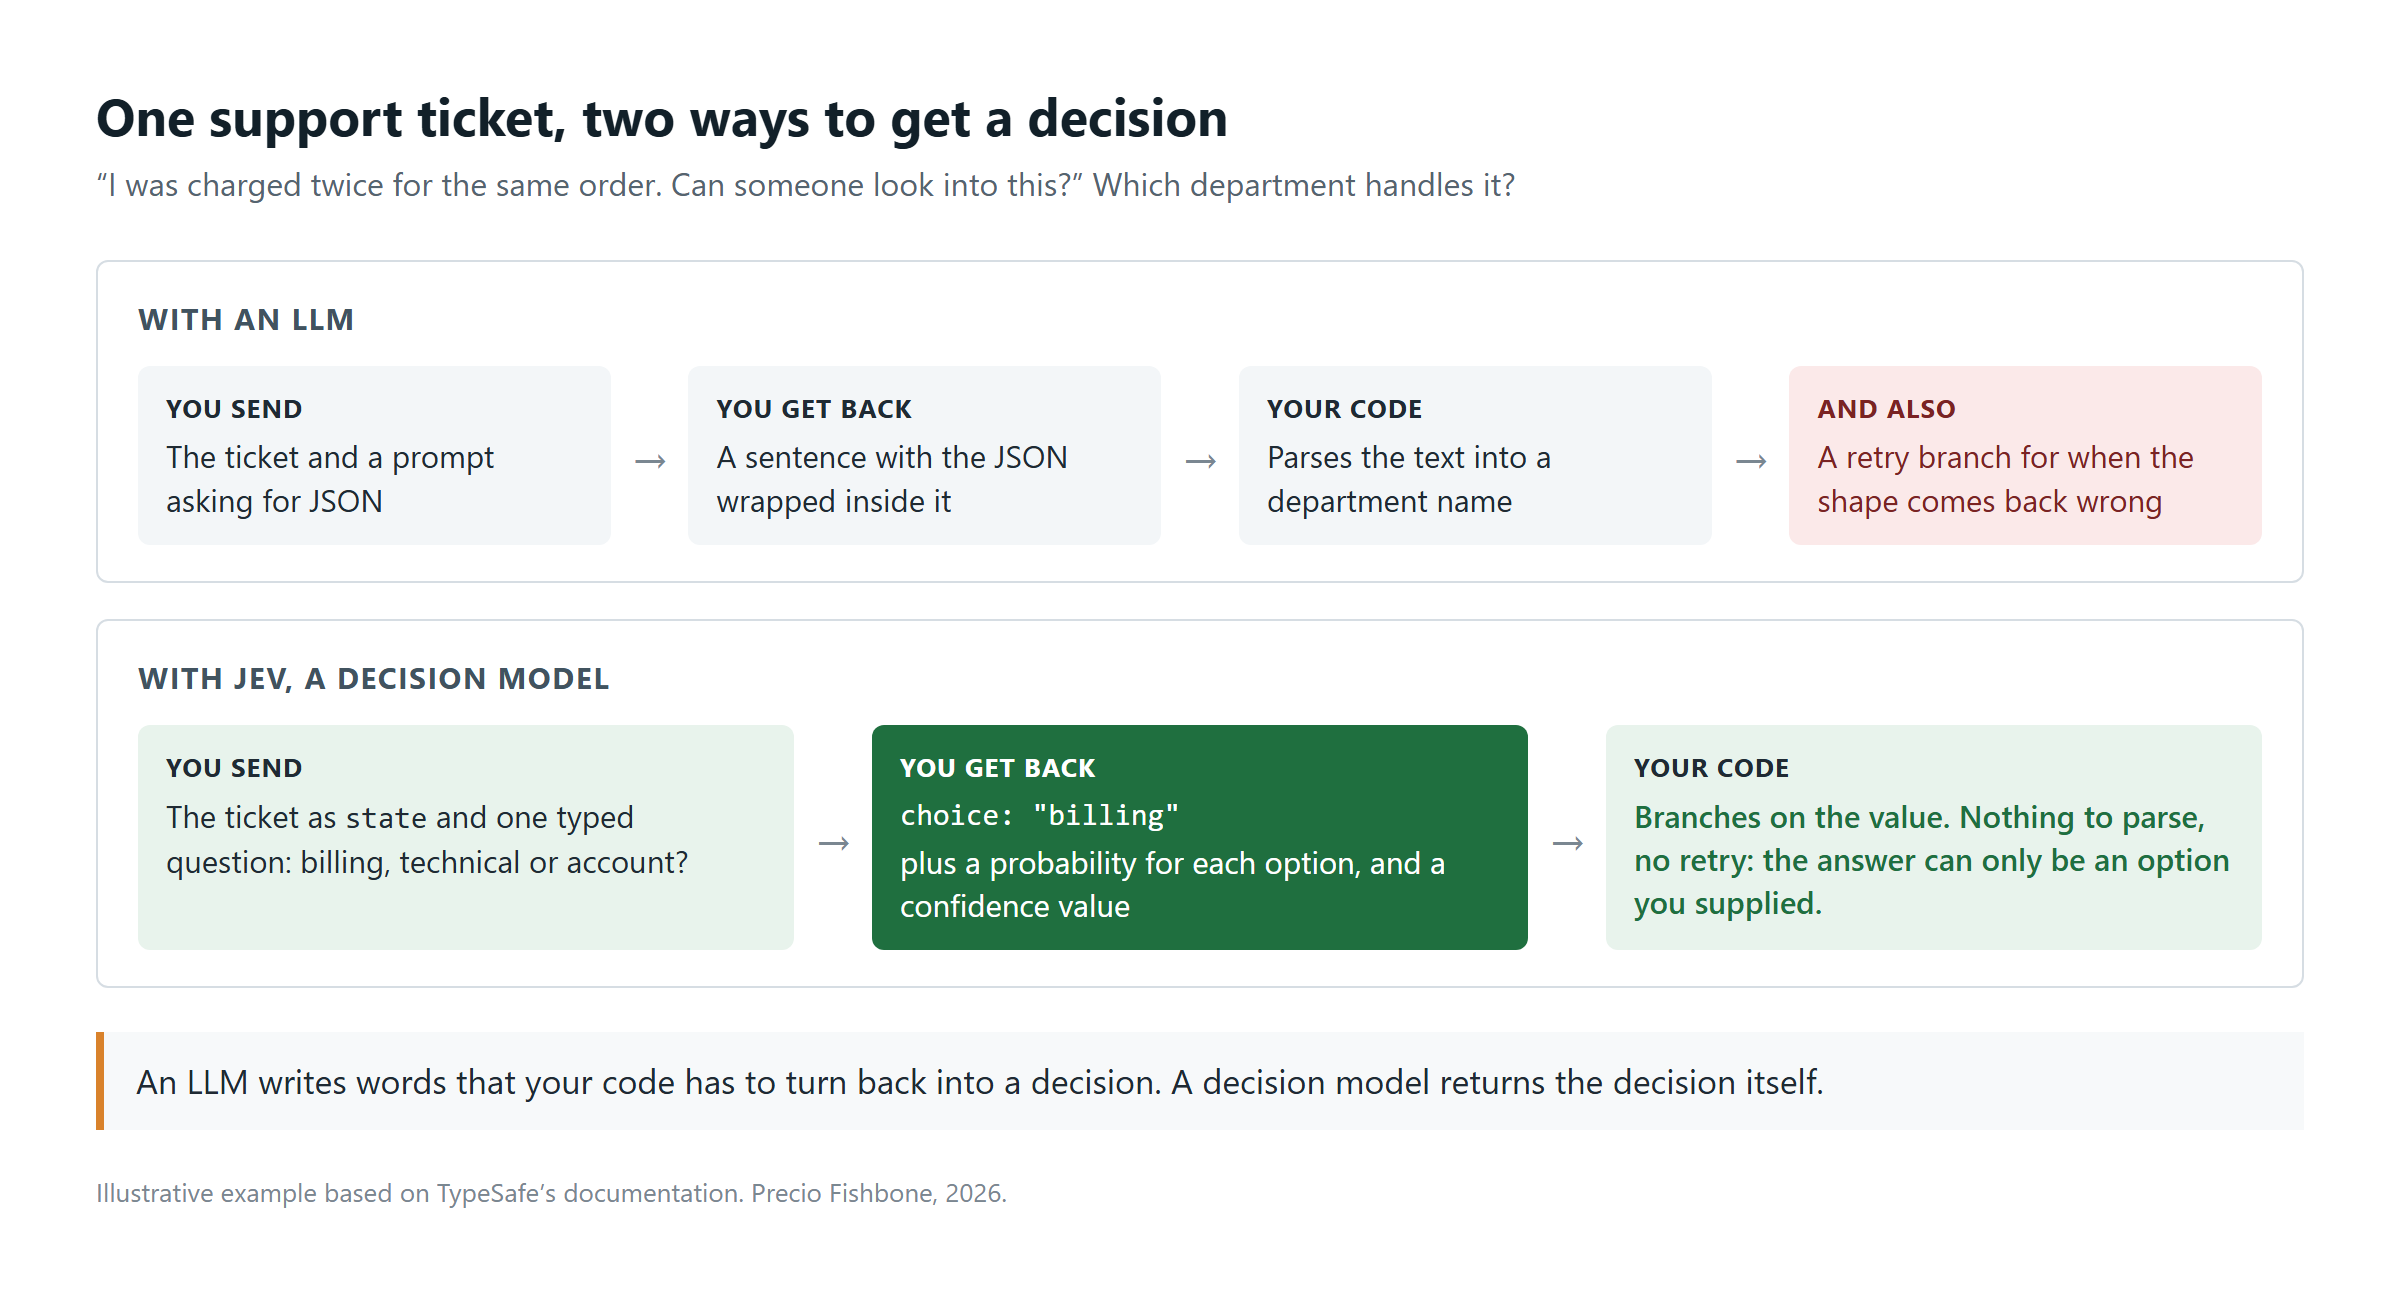
Figure 1. One support ticket, two ways to get a decision. View full-size image
Who Built Jev
TypeSafe AI was founded in 2024, spent two years in stealth, and raised a $40 million seed round led by DCVC at a $200 million valuation.
CEO Diogo Almeida is a co-author of OpenAI’s InstructGPT paper, the work that put RLHF into ChatGPT, and was at Google Brain before that. CTO Erik Gafni is a repeat founder in production AI systems, and COO Sasha Sheng is a former research engineer at Meta/FAIR.
Where the Name Comes From
System One comes from Daniel Kahneman’s Thinking, Fast and Slow, where System 1 is fast and intuitive and System 2 is slow and deliberate. Jev is aimed at System 1: the judgment a knowledgeable person makes in a few seconds without deliberating.
Jev itself is short for William Stanley Jevons, the economist behind the Jevons paradox. More efficient steam engines burned more coal, not less. The bet, named in TypeSafe’s launch post: make machine judgment cheap enough and organisations will not spend less on it, they will put it in a thousand more places.
How Jev Differs from an LLM
Jev is not a smaller LLM. It is trained on a different objective and returns a different kind of output.
| LLM | Jev | |
| Returns | Free text you parse | A typed value your code branches on |
| Trained with | RLHF (human preference) | RLCD (Reinforcement Learning for Calibrated Decisions) |
| Uncertainty | Rarely stated, often overconfident | Probability across every option, plus a confidence value |
| Wrong answers look like | Plausible prose | A wrong option from your list, never an invented one |
| Input | Text, images, audio | Text only |
The word doing the work is calibrated. TypeSafe trains the probabilities against outcomes, so answers reported at 0.8 should be right about 80% of the time. That holds across groups of predictions, not for any single answer.
The marketing says “zero hallucinations”, which is narrower than it sounds: Jev cannot invent an answer outside your options, but it can still put 0.9 on the wrong one.
Decision Models Fill the Gap Between Rules, Classifiers and LLMs
The name decision models comes from Simon Willison and Maggie Appleton, and it is more useful than System One because it says where Jev sits: next to three tools most IT departments already run.
| Needs | Microsoft tool you already have | Breaks when | |
| Rules | A developer | Conditions in Power Automate or code | The condition can no longer be written down |
| Trained classifier | Labelled data and retraining | Custom text classification in Azure Language | Categories change, or no labelled data exists |
| Decision model | A question and options in plain words | Nothing inside Azure today | Numbers, dates or hostile input |
| LLM | A prompt | Models in Microsoft Foundry | You pay for text nobody reads |
The row that matters in a Microsoft estate is the second one. Custom text classification retires from Azure Language on 31 March 2029, and Microsoft directs new projects to Microsoft Foundry and its language models. The middle of the table is emptying just as the cost of filling it with an LLM becomes visible.
My rule of thumb: keep rules where you can write the condition, keep a trained model where categories are stable and labelled, and consider a decision model only for the branches that currently wake an LLM to return one word. What you can ask a decision model comes in three shapes.
The Three Question Types
Jev exposes three primitives.
| Type | The question | What comes back |
| Choice | Pick one option from a defined set | The selected option, a probability for every option, confidence |
| Score | Rate the state against levels you describe | A position along your levels, which can land between two, plus probabilities and confidence |
| Noul | Is this statement true? | A single number from 0 to 1 |
A Choice takes up to 255 options, and TypeSafe’s advice is to send the whole list, since each option costs only a few tokens. A Score’s levels are yours to define, so “0 = calm, 1 = frustrated, 2 = very frustrated” can come back as 1.4. A Noul carries no confidence value. All three mix in one call, evaluated in parallel against the same state.
Confidence is what turns this from a classifier into an architecture: a single number from 0 to 1 derived from how concentrated the probability is. The standard pattern splits it three ways, acting automatically above a high threshold, asking for confirmation in the middle, routing to a person at the bottom, with the threshold scaling to the stakes.
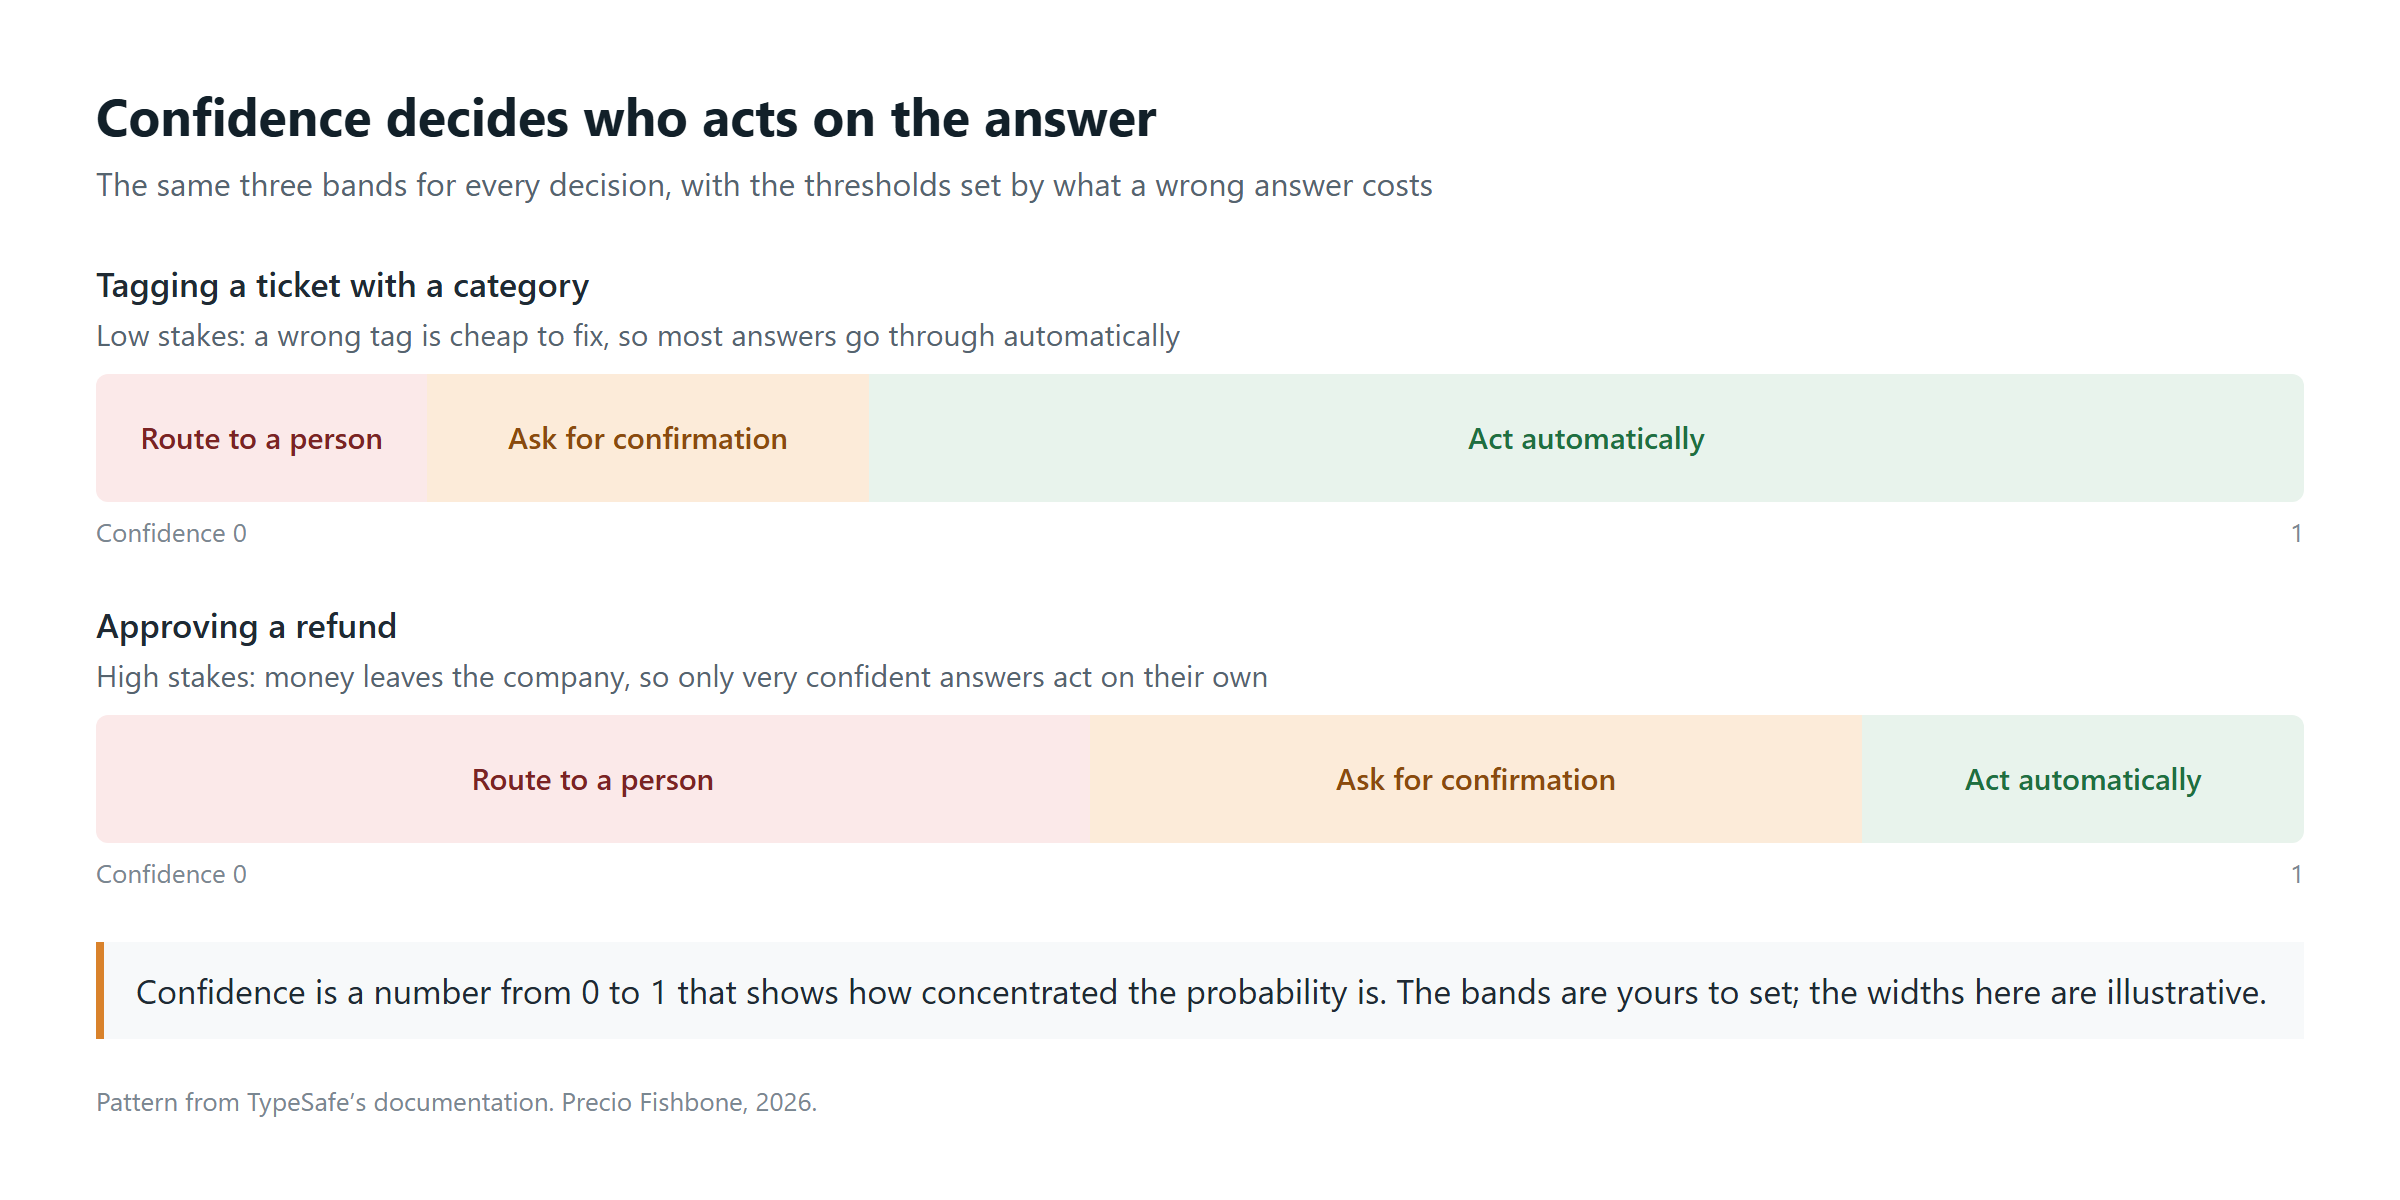
Figure 2. Confidence decides who acts on the answer. View full-size image
What People Use Jev For
Vercel’s launch data and TypeSafe’s cookbooks point at the same jobs, and most are agent control flow: choosing the next tool or subagent, and deciding whether a workflow continues, retries, asks the user or stops. The rest is grading before code acts on the grade, from urgency and risk to jailbreak screening, plus routing tickets and re-ranking retrieved passages.
Every job here has the same shape. Somewhere there is a branch, and a language model is asked to produce a sentence purely so that code can read it and take the branch. Tool selection in agentic AI workflows is the clearest case, but relevance filtering in RAG architecture and the classification step in document processing are the same branch elsewhere. What each needs is a value, not the sentence wrapped around it.
Jev’s Strengths and Limits
TypeSafe publishes a jaggedness page for jev-1.13 listing its own failure modes, dated 17 September. It is the vendor’s own list, not my guesswork.
Jev is good at common-sense semantic judgment on text: does this express urgency, which category fits, how severe is this complaint. It is also very consistent, so similar inputs return similar numbers, which keeps a confidence threshold steady in production.
It struggles with anything that is a number wearing a sentence. It does not count reliably, it reads dates as text instead of ordered quantities, and indirection costs accuracy. It is also literal, answering the question you wrote instead of the one you meant.
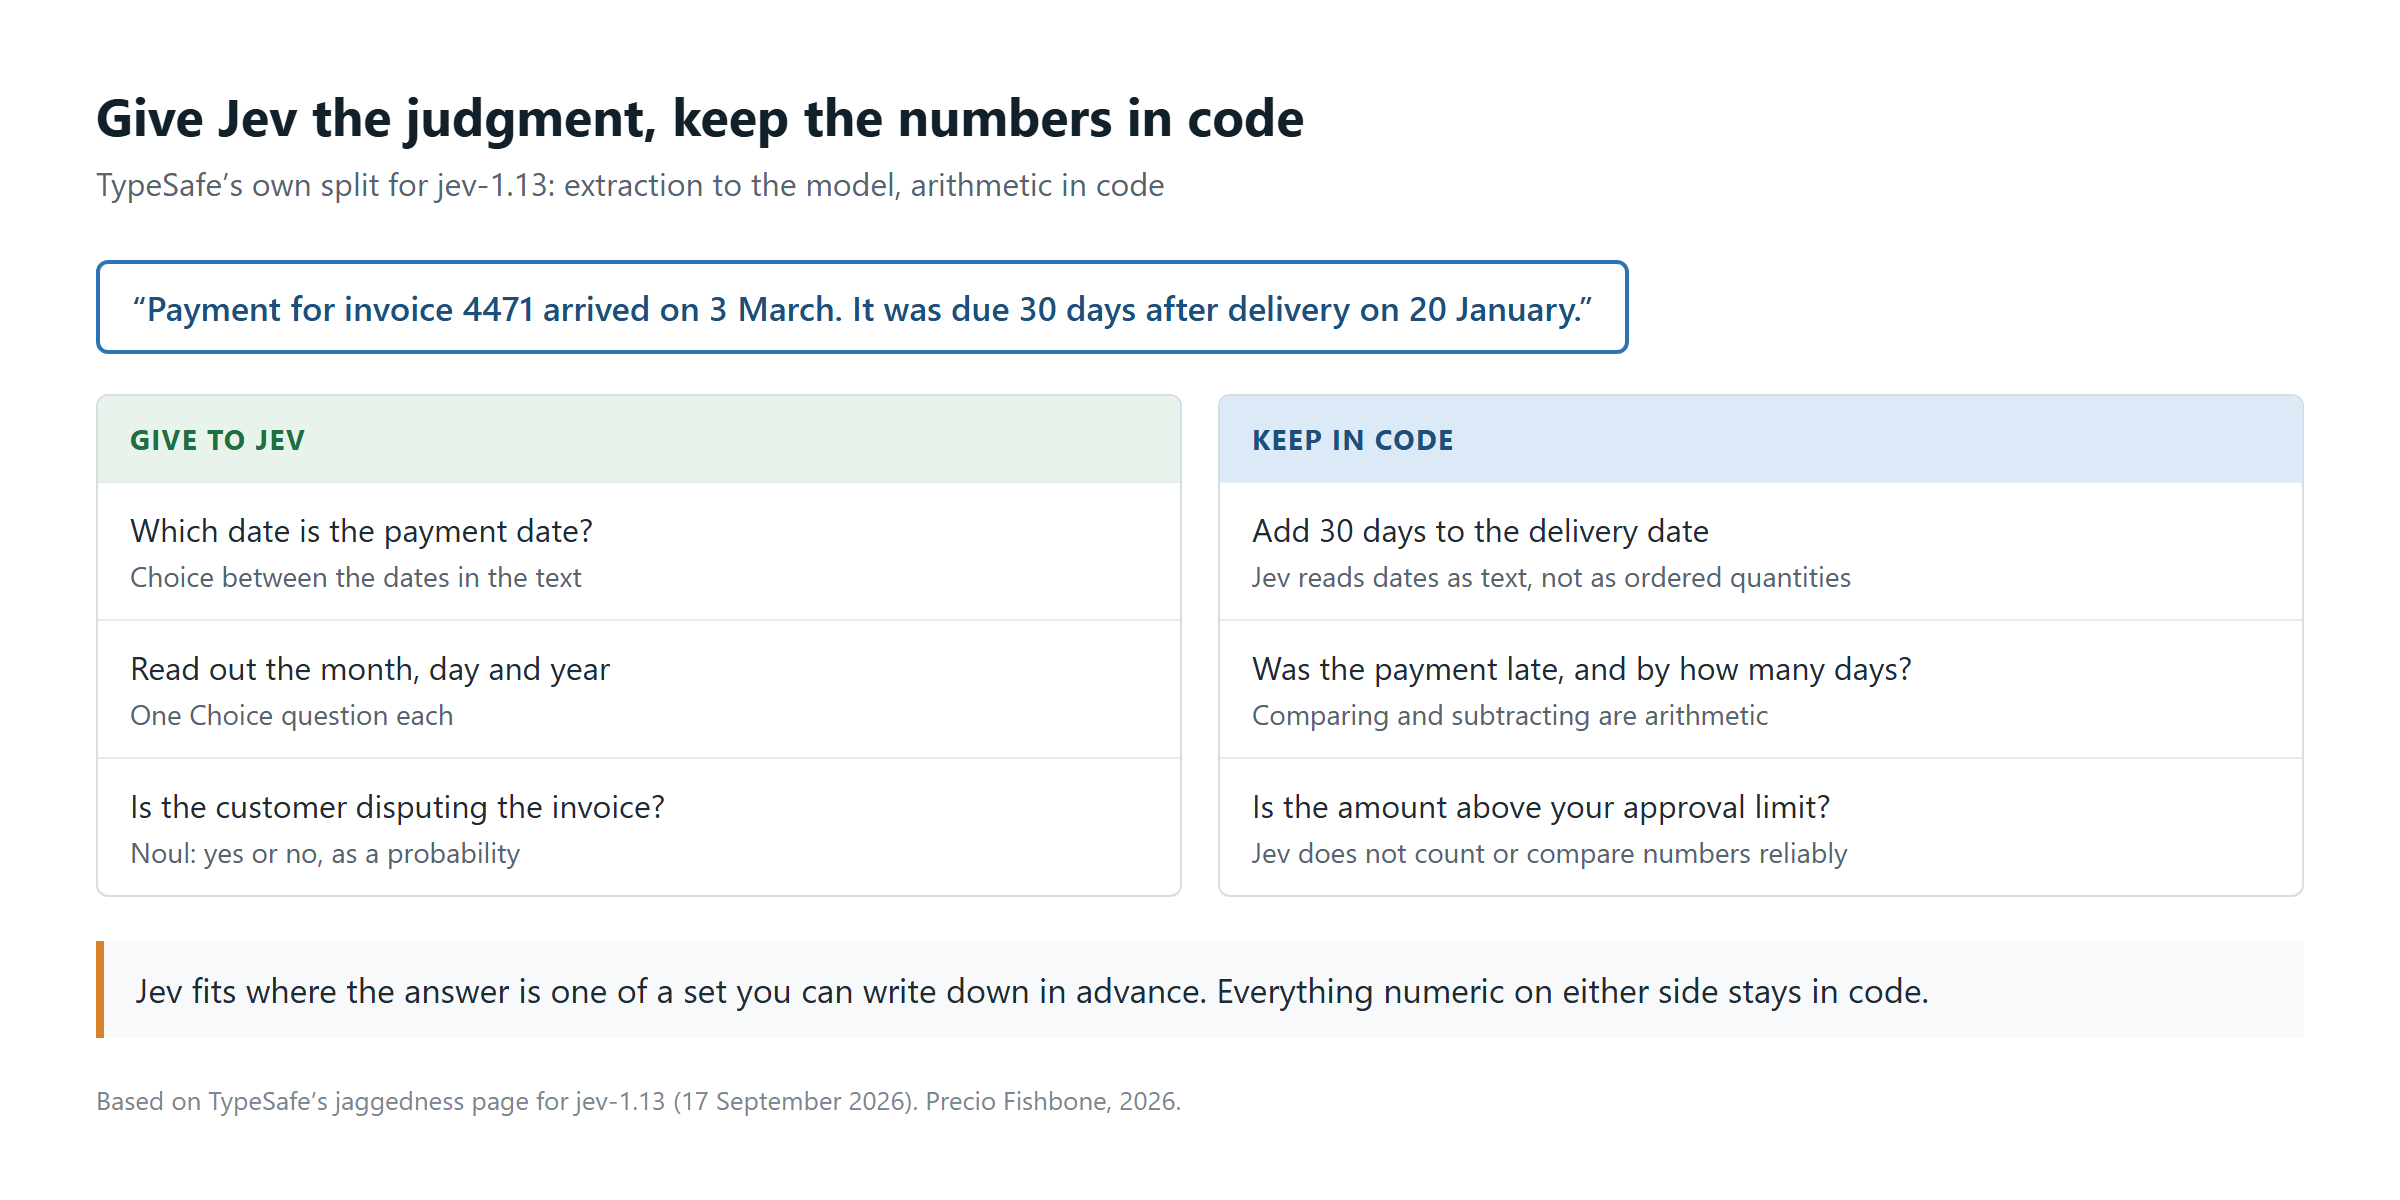
Figure 3. Give Jev the judgment, keep the numbers in code. View full-size image
Two limits belong in a risk register, not a capability list. The first is adversarial input: state is data, and Jev does not treat it as hostile, so injected text can move a verdict. A VentureBeat security review found Jev reaching agent infrastructure faster than anyone had worked out how to audit it. A decision leaves no prose behind, so “0.83” is not an explanation for an auditor, which is the AI risk management problem in a new shape.
The second is that structural invariants do not hold. The same refund question returns 0.22 as a Noul and 0.01 as a Choice, and a question plus its negation sums to 1.19. A threshold tuned on one primitive will not carry to the other.
So the rule is a shape rule, not a domain rule: Jev fits where the answer is one of a set you can write down in advance and code owns everything numeric on either side. Test on Swedish or Norwegian content first.
What It Costs and How Fast It Is
Current model jev-1.13.0, with the aliases jev-latest and jev-preview. The figures below are from TypeSafe’s model documentation.
- Price: $0.042 per million input tokens, or $42 per billion. Output tokens are free.
- Latency: 0.114 seconds on TypeSafe’s own site. Independent tests have measured roughly 140 to 710 ms.
- Context: 64k tokens per request; 32k for the state plus the longest single question.
- Rate limits: 250,000 tokens per second and 1,200 requests per minute, subject to change while demand is high.
- Data handling: the same weights serve every account, no per-customer fine-tuning, no training on customer requests, and zero data retention for enterprise.
The headline on TypeSafe’s own site is 193.6x faster and 444.6x cheaper, with a 238x lower input price than Claude Fable 5.1. These come from TypeSafe’s own evaluations, with no public benchmark behind them, so treat the multiple as a ceiling.
How to Get Access to Jev
TypeSafe opened sign-up to everyone on 20 September, then paused new direct sign-ups on 22 September after a surge in demand. Existing accounts keep working, and the gateway routes below do not depend on it.
| Route | What it is | When to use it |
| Playground | Browser console at console.typesafe.ai. Paste text as the state, add a question, read the answer. | The first fifteen minutes, no code |
| API | One endpoint, POST /v1/systemone, with a key from the console and official Python and JavaScript SDKs |
Building it into your own service |
| Vercel AI Gateway | Model id typesafe-ai/jev, zero data retention and no training when you turn them on |
You already route models through the gateway |
| OpenRouter | Model ids typesafe/jev-1.13 and jev-latest, plus Jev Router, which uses Jev to pick an LLM per request |
You already route models through OpenRouter |
| Cloudflare Workers AI | Model id typesafe/jev, same $0.042 per million input tokens, zero data retention | You already run workloads on Cloudflare |
The documentation carries a long cookbook section. On 25 September TypeSafe also added Jev Router to OpenRouter, a free router that uses Jev to pick which LLM answers each request.
If Your Agents Run on Azure
The question that decides anything is whether the branch decisions in your workflows need a frontier model at all, and if not, whether fixing that requires a new vendor.
Jev is not in the Microsoft Foundry model catalog, so every call to it leaves your Azure tenant. There is a version that stays inside the platform you already govern. Model Router in Azure AI Foundry picks the most cost-effective model per request within a quality band you set, and honours data zone boundaries. Sweden Central and Norway East support Data Zone Standard. Your agent identities stay in Entra Agent ID instead of a second set of API keys. It saves less per token, and it keeps a company whose first product is only weeks old out of your data processing agreements.
I have worked that trade-off through in a separate piece on the cost of LLM decisions in Azure AI Foundry. For now the useful exercise costs nothing: open your Foundry logs and count how many calls in your busiest workflow return text no human ever reads.
Work with Precio Fishbone
Wondering which of your AI workloads actually need a frontier model? Book a free consultation with our AI team, or email me directly at par.johansson@preciofishbone.se.
Book a free consultationFrequently Asked Questions
Is Jev an LLM?
No. It reads natural language like one, but it is trained with RLCD instead of RLHF and returns typed values with probabilities. It produces no text.
What is TypeSafe AI?
The San Francisco company that builds Jev, founded in 2024 by Diogo Almeida, Erik Gafni and Sasha Sheng, funded by a $40 million seed round led by DCVC.
What is RLCD?
Reinforcement Learning for Calibrated Decisions, the algorithm TypeSafe trained Jev with. It optimises probabilities against outcomes so they reflect real uncertainty, instead of optimising output for human preference the way RLHF does.
Can Jev replace our LLM?
No. It covers the decision points; generation, summarisation and dialogue still need a language model. Usually both run together, with Jev choosing which path the expensive model is used on. A Jev browser agent works this way: a language model plans the task and Jev picks each click.
What is a decision model?
A model that reads text and returns a typed answer, such as an option, a yes/no probability or a score, each with a probability attached, instead of generating text. Simon Willison and Maggie Appleton coined the name; TypeSafe calls the category System One models, and Jev was the first to ship.
Share this on
Pär Johansson
Pär works with international business at Precio Fishbone, project delivery & digital services, helping turn complexity into progress and strategy into long-term value. With many years of experience in international business, He is known for building strong relationships and turning plans into meaningful progress. Driven by people, trust and sustainable growth.